AI AGENT EVALUATION

Prove your AI agents before your customers do.

With Simulator from NiCE Cognigy, stress-test AI agents across thousands of realistic conversations. Measure them against explicit success criteria, compare variants and ship consistent outcomes to production.

Show how agents behave under pressure, before launch.

More AI agents are going live, but few teams can show how they'll perform. Simulator runs large-scale evaluations to show how agents behave under pressure, before launch.

Use data, not assumptions, to prove AI agents are ready for real-world complexity.

Confidence before deployment

Stress-test happy paths, edge cases and failure scenarios, and ship only when performance meets your standards.

Faster iteration, less risk

Replace slow, manual QA with automated evaluations, instant scoring and clear next steps, and release faster.

Enterprise-grade reliability at scale

Keep performance consistent as agents evolve, flows change, integrations update and foundation models shift.

Continuous evaluation for agentic AI

Mirror real customer behavior

Define test scenarios with synthetic customers that reproduce real language, intents and edge cases. Each scenario pairs a persona, a mission and success criteria, so results are measurable, not subjective.

Write your own scenarios or generate them from existing AI agents and real transcripts.

Run evaluations at scale

Run simulations on demand, on a schedule or as part of automated regression testing. Broad sets of naturally varied conversations surface the rare behaviors you'd only find through extensive testing.

Model real-world dependencies

AI agents depend on APIs and backend systems, and every response path adds complexity: timeouts, server failures, authentication issues and alternate success paths.

Simulator mocks the full range of third-party responses, from success to degradation to error, so you see how agents respond without touching live systems. That hardens mission-critical integrations and reduces production risk.
Score, compare and improve

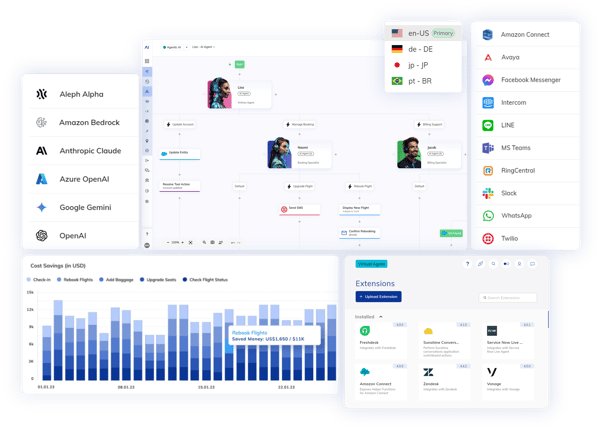
Score results automatically against configurable criteria. Drill into failed conversations to find the friction and see exactly what needs to change.

Track success rates over time to catch regressions early and validate every update.

What Simulator proves

Five measures that show, with data, whether an AI agent is ready for production.

Task success and goal completion

Did the AI agent resolve the customer's mission?

Guardrail and policy adherence

Did the AI agent stay within compliance and safety boundaries?

Integration and tool performance

Did API calls, workflows and backend processes behave as expected, even in adverse conditions?

Experience quality

Was the conversation clear, helpful and on-brand?

Multilingual consistency

Did performance hold up across languages, regions and customer segments?

See Simulator in action

Introducing Simulator: AI Agent Evaluation for Real-world Confidence

From testing to continuous evaluation.

Stress test AI agents with simulator,